A repeatable way to release.
Versioned pipelines and infrastructure, with review gates and a tested way back.
In your repository: Pipelines, Infrastructure as code, A tested way back.
In your repositories, owned by your team.
Senior engineers for delivery pipelines, infrastructure, and observability. A clearer path to production, with a team that knows how to run it.
Your team keeps operational ownership, supported by technical review from Inpro Analytics.
From repeatable releases to reliable operations. Explore the work and the first improvement your team can use.
Today: Every deploy needs coordination.
Version your pipelines and infrastructure. Promote the same artifact through development, staging, and production, with explicit checks and a way back.
First useful milestone One service shipping through a reviewed pipeline, with a tested recovery path.
Today: Too many alerts, too little context.
Connect availability, latency, and successful requests to service-level objectives. Agree thresholds, escalation rules, and who responds.
First useful milestone One service with agreed reliability targets and alerts your team can act on.
Today: Every new service starts from scratch.
Bring maintained service templates, CI checks, and self-service environments into one documented workflow with the right guardrails.
First useful milestone One documented path a team can use to ship a service end to end.
Scope and timing are agreed after discovery.
Working systems in your repositories, with guidance your team can use to maintain them.
Versioned pipelines and infrastructure, with review gates and a tested way back.
In your repository: Pipelines, Infrastructure as code, A tested way back.
In your repositories, owned by your team.
Service objectives, useful dashboards, and alerts with a named owner.
Dashboards + response rulesRecovery rehearsed with the people on call. Runbooks and responsibilities agreed.
Runbooks + recovery rehearsalAnonymized engagements, each with the team we placed, how long it ran and what it changed.
We agree the scope around your platform and the team running it. Each stage leaves a working improvement behind.
Review the deployment workflow, recent incidents, and the work your team repeats by hand. Agree on the first constraint to remove.
Result A focused reliability assessment
Build GitOps delivery and infrastructure as code around one service. Review the gates, permissions, and rollback before expanding.
Result A tested path to production
Agree on service-level objectives, connect dashboards to user experience, and review when an alert should reach a person.
Result Clear targets and actionable alerts
Rehearse recovery, work through the runbooks, and agree on ownership, on-call rotation, and ongoing support. Your team operates what we build.
Result An operational handover
You meet and interview the engineers. We agree rates, availability, access, and operational responsibilities before the engagement starts.
Meet the companyAn indicative platform plan allows one to two weeks for assessment and two to three weeks for the initial pipeline and infrastructure work. Reliability improvements continue through delivery, with a broader operational handover in month four or later. We agree the scope and timing around your needs; a single-service improvement can be smaller.
No. We start with your current environment and the delivery problem. Improving a pipeline, infrastructure module, or monitoring setup may be the right scope without changing the platform.
Yes. Engineers join your repositories, review process, and working routines. You interview the people first, and we agree responsibilities with your team before work starts.
Support hours, escalation responsibilities, and any on-call participation are agreed for each engagement. They are not assumed to be included in a standard engineering engagement.
Meet your specialists.
Select a person to explore their experience.
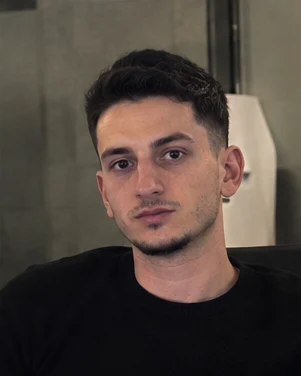
Showing Dardan, DevOps Engineer
Cloud & DevOps
DevOps Engineer
6 yearsCI/CD and observability

DevOps Engineer

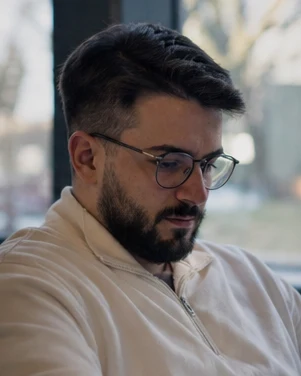
Cloud & DevOps
Cloud / DevOps Engineer
10 yearsplatform and reliability

Cloud / DevOps Engineer
You interview and approve every engineer. We review technical experience, working style, and language fit.
Typically 1-3 senior engineers, with an indicative rate of €290-450 / day per engineer. Shortlist target: 5 business days from an agreed brief.
Indicative sequence. We confirm timing, capacity, and terms for your role.
Sample profiles from our network. Availability, rates, and fit confirmed for your brief. Language levels use CEFR; full CVs and interview details accompany your shortlist.
Connect your release workflow to the systems that run and observe it. We build around your existing platform.
Talk through your stackWe work with your existing stack and choose the tools around the job. These are the ones we use most in this area.
Move reviewed changes through a repeatable release process.
Define and review infrastructure in the same way as application code.
Run services on a consistent foundation, with the controls your team needs.
Understand service health through useful metrics, logs, and traces.
Connect useful signals to clear ownership and a response.
Give engineers shared tools, templates, and appropriate access.
Tell us where releases get difficult. We’ll review your workflow with you.